Files uploaded during Claude's incognito chat sessions are logged in User Settings under Privacy and Data, making them retrievable after the session ends. Incognito mode does not prevent file metadata from being stored, contrary to user expectations. The discovery was made by a researcher testing Claude's privacy boundary on personal accounts.
/12 Sep 2026/Rreddit
Multiple Claude users report that Projects workflows, including local folder connections and website access, stopped working overnight with no announcement from Anthropic. The disruption affects local file and browser integrations that were previously stable. Users are questioning whether the change is intentional or a regression.
/12 Sep 2026/Rreddit
OpenAI's GPT-6 Astra has taken the top position on VerBench, a benchmark measuring model reliability and factual accuracy. The result pushes Anthropic's Opus 4.6 down the leaderboard in this evaluation category. Community reaction is divided on VerBench's real-world relevance compared to task-specific evaluations.
/12 Sep 2026/Rreddit
A popular r/ClaudeAI thread reflects on Opus 4.6 as the model that best matched community expectations for directness, practical depth, and clear output. Commenters describe a perceived shift in later model versions toward more hedged, safety-padded responses. The discussion has drawn thousands of upvotes and surfaces a recurring tension between capability and guardrails.
/12 Sep 2026/Rreddit
A new AI model leaderboard with updated rankings has been shared on r/ClaudeAI, drawing significant community discussion about model placement relative to real-world experience. The thread highlights gaps between leaderboard scores and user-perceived quality. Specific model rankings are contested in the comments.
/12 Sep 2026/Rreddit
OpenAI has confirmed via a public post that de-identified user conversation data is used to train and improve ChatGPT. The disclosure revives debate about what de-identification means in practice and whether users have meaningful control over opt-out. The confirmation follows renewed scrutiny of AI training data practices across the industry.
/12 Sep 2026/YHN
Anthropic has updated its terms to require users to be 18 or older to use Claude, implementing age assurance measures. The policy change may affect education-focused and youth-facing use cases previously built on Claude's API. Anthropic's support page outlines the age verification process and exceptions.
/11 Sep 2026/YHN
Deepseek appears to have quietly phased out Deepseek V4 Pro without an official announcement. Community members noticed the model becoming unavailable on the platform, prompting discussion about the company's model lifecycle practices.
/10 Sep 2026/Rreddit
A researcher found that Qwen 3.8B will follow GPT-5.5 Pro reasoning prefill tokens and adopt that model's reasoning style. The finding suggests smaller open models can be steered via prefill injection to produce reasoning patterns characteristic of much larger proprietary models.
/9 Sep 2026/YHN
Sebastian Raschka analyzes GPT-6 Astra and looped transformer architectures, examining how hidden reasoning mechanisms might work in next-generation models. The piece covers technical proposals for internalizing reasoning without visible chain-of-thought steps and what that means for evaluating model behavior.
/9 Sep 2026/YHN
A developer blog post catalogs effective prompt patterns for stripping LLM-typical stylistic habits, including direct instructions to remove mannered prose and filler language. The post compiles a set of tested incantations for shaping LLM output register and style.
/8 Sep 2026/YHN
OpenBMB released MiniCPM5-2B, which scores 15 on the Artificial Analysis Intelligence Index v4.2, the highest of any open-weights model at 4B parameters or below. The model is available on Hugging Face.
/8 Sep 2026/Rreddit
A daily Claude user with over a year of heavy coding use tried GPT Astra and shared detailed comparative observations on response style, coding workflow fit, and where each model differs in practice. The post is gathering discussion from users who actively switch between Claude and competing assistants.
/8 Sep 2026/Rreddit
OpenAI's GPT-6 Astra model appeared on OpenRouter, giving developers access through a third-party aggregator without managing a separate OpenAI API key. The listing confirms standard per-token pricing through the OpenRouter platform. Teams already using OpenRouter for multi-provider routing can now add GPT-6 Astra to their stack without changing infrastructure.
/4 Sep 2026/YHN
Nvidia has announced a definitive agreement to acquire Hugging Face, the dominant platform for open AI model hosting and collaboration, for $12.9 billion. The deal gives Nvidia direct control over the largest community hub for AI models, datasets, and inference tooling. Community reaction focuses on concerns about platform neutrality and what this means for open-source AI distribution.
/4 Sep 2026/Rreddit
IFM released K2 Horizon, a new open model family claiming frontier-level performance with a permissive license. The announcement follows the earlier K2 series and comes with community-produced GGUF quantizations already available. K2 Horizon positions itself as an open alternative to closed frontier models for users running local inference.
/4 Sep 2026/Rreddit
The ARC Prize team published benchmark results for GPT-6 Astra on ARC-AGI-3, the latest version of the Abstraction and Reasoning Corpus. The results show a substantial improvement over previous models. ARC-AGI-3 is designed to be resistant to memorization and tests genuine reasoning ability.
/3 Sep 2026/YHN
OpenAI officially launched GPT-6 Astra, its next-generation flagship model. The model is rolling out to ChatGPT subscribers and the API. This is the first major model release since GPT-5 and represents a significant capability jump in reasoning and multimodal tasks.
/3 Sep 2026/YHN
OpenAI has started rolling out GPT-6 Astra to users, according to CNBC. The rollout is gradual and begins with paid ChatGPT subscribers. The release follows months of preview access and positions Astra as OpenAI's most capable publicly available model.
/3 Sep 2026/YHN
Quasar 438B has been released as Europe's largest and most capable large language model to date, with 438 billion parameters. The model is positioned as a competitive alternative to leading US and Chinese frontier models. It represents a significant milestone for European AI development.
/3 Sep 2026/YHN
Meta has released Muse Spark 1.3, reported to match the performance of Anthropic's Fable 5 at significantly lower prices: $0.10 per million input tokens and $0.20 per million output tokens. The model is available through Meta's developer platform. Pricing makes it one of the more cost-competitive frontier-class options currently available.
/3 Sep 2026/Rreddit
A developer analyzed 22,022 API calls and found Fable 5.1 uses approximately 31% more tokens per prompt compared to Fable 5, a difference that only surfaces when comparing per-prompt metrics rather than per-call counts. For heavy API users, this effectively reduces how many tasks fit within usage limits without triggering rate caps. The data comes from a real production workload rather than a benchmark.
/3 Sep 2026/Rreddit
A MineBench comparison of 15 builds found Fable 5.1 averaged 40 minutes 12 seconds per build vs 18 minutes 4 seconds for Fable 5, at a total cost of $147.55 vs $54.93. The newer model generates significantly larger JSON outputs (34 MiB average), which accounts for the higher cost and longer runtime. Output quality improvements are noted but the resource increase is substantial.
/3 Sep 2026/Rreddit
A user reports that Fable 5.1 Max produced a local AI setup guide that accurately accounted for hardware constraints, available models, and realistic performance expectations. Previous models reportedly gave setup recommendations that were impractical or overpromised. The post has generated discussion comparing Fable 5.1's practical advice to other frontier models.
/3 Sep 2026/Rreddit
Fable 5.1 outputs contain imperceptible watermarking embedded in the generated text, included to satisfy EU regulatory requirements. Legal professionals are advised to verify AI-generated content before submitting it in court contexts, as these markers can identify text as AI-produced. The post explains what attorneys specifically need to know about handling Fable 5.1 output.
/3 Sep 2026/Rreddit
Baseten published an analysis of the cost-quality-latency tradeoff space for LLM inference, framing it as an efficient frontier problem borrowed from portfolio theory. The post explores how batching, quantization, and hardware choices shift models along the frontier and identifies operating points suited to different production workloads. It provides a practical framework for choosing inference configurations based on application requirements.
/2 Sep 2026/YHN
WorldLabs introduced Atlas, a world model built for spatial intelligence and persistent 3D environment understanding. The model generates and reasons about structured 3D scenes from visual input, targeting robotics, simulation, and spatial reasoning applications. The blog post outlines the architecture and early capabilities of this approach to grounded world modeling.
/2 Sep 2026/YHN
Anthropic released Claude Fable 5.1 and Claude Mythos 5.1, its most capable models for coding and long-running agentic tasks. Fable 5.1 scores 52.6% on Terminal-Bench-Science and 73.4% on CursorBench, surpassing all prior Claude models. Pricing drops roughly 25% for typical workloads and 45% for agentic use, with cache read costs cut 75%. Mythos 5.1 is the same model with restricted access and additional enterprise safety controls (API ID: claude-fable-5-1).
/2 Sep 2026/YHN
DeepSeek has released DeepSeek-V4-Flash-Vision-Exp on Hugging Face, adding vision and multimodal input handling to the existing V4 Flash architecture. The experimental release is available for download and local testing. Community members are running early benchmarks on visual reasoning and code generation from screenshots.
/1 Sep 2026/Rreddit
Apple released updated Mac mini and Mac Studio models ahead of schedule, driven by unexpected enterprise demand for local AI hardware. Fulfillment challenges arose from global memory shortages and the lack of dedicated business and developer relations teams. Some orders shifted to Nvidia as a result.
/1 Sep 2026/YHN
Apple has accused OpenAI of destroying evidence in an ongoing trade secrets lawsuit. The dispute centers on former Apple engineers who allegedly brought proprietary code to OpenAI. The accusation of evidence destruction significantly escalates the legal battle between the two companies.
/1 Sep 2026/YHN
The US government quietly sold an Anthropic equity stake seized from former FTX executives, a position now estimated to be worth up to billion. The sale was handled without public announcement. The original stake came from FTX's pre-collapse investment in Anthropic during its early funding rounds.
/1 Sep 2026/Rreddit
Nvidia has agreed to acquire Hugging Face for $12.9 billion, bringing the largest open-source AI platform under hardware giant control. The deal would give Nvidia direct influence over the model repository and tooling that much of the AI ecosystem depends on. Community reaction has been largely skeptical, with concerns about open-source access and potential hardware lock-in.
/28 Aug 2026/Rreddit
Anthropic has published a research preview of a Model Hardware Standard, a proposed framework for describing the hardware requirements of AI models in a consistent and portable format. The standard aims to make it easier to match models to suitable hardware across cloud and local deployments. The preview is open for community feedback before a final specification is published.
/28 Aug 2026/YHN
Multiple users on r/ClaudeAI reported a noticeable overnight improvement in Opus 5 performance, describing longer, more detailed responses and substantially greater reasoning effort compared to earlier that same day. The change was observed across different task types including code generation and analysis tasks. Anthropic has not announced any model update.
/28 Aug 2026/Rreddit
The team behind Apodex 1.1, a model family designed for agentic intelligence on complex tasks, held an Ask Me Anything session on r/LocalLLaMA. The thread covers technical questions about model architecture, context handling, training approach, and planned future releases. The team described their focus on scaling agentic reliability rather than benchmark-optimized general performance.
/28 Aug 2026/Rreddit
A researcher published an analysis of what they call the load-bearing vocabulary of Claude, the small set of token sequences that account for a disproportionate share of Claude's output across many different tasks. The study identifies clusters of phrases that appear across diverse response types and may shape the model's default conversational style. The work is framed as a tool for understanding and auditing large language model behavior.
/28 Aug 2026/YHN
Chinese AI lab Z.ai has confirmed that Ox Alpha, a model that posted strong benchmark results without public attribution, is built on the GLM series. The company says it will open-weight the model. Bloomberg reported the identification based on technical analysis and company confirmation.
/27 Aug 2026/YHN
OpenAI's head of data centers departed the company, according to a Wall Street Journal report. The exit comes as OpenAI is aggressively expanding its infrastructure capacity to support next-generation model training and inference workloads.
/25 Aug 2026/YHN
SemiAnalysis reports that OpenAI's custom AI chip, codenamed Jalapeño, outperforms Nvidia's Blackwell architecture on key inference metrics, a significant claim if accurate. The analysis suggests OpenAI could meaningfully reduce its dependence on external GPU supply for training and inference.
/25 Aug 2026/YHN
Reports surfaced via a post by hardware analyst Ching-Po Hsu indicating Apple is developing an M5-based server product for AI inference workloads. If accurate, an M5 server would give Apple a unified silicon path from personal devices to cloud-scale inference on the same architecture. No official announcement has been made by Apple.
/25 Aug 2026/Rreddit
Xiaomi announced the AI Cube, a prototype three-chip AI inference system combining its Xuanjie O3, O100, and D100 processors in a single package with 1.2 TB/s of aggregate memory bandwidth. The system is positioned to compete with Nvidia-based inference appliances and Chinese domestic AI accelerators. Detailed production timelines and pricing have not been announced.
/25 Aug 2026/Rreddit
Qwen 3.8 27B has reached 9th position on Code Arena, a benchmark ranking models by performance on real-world developer coding tasks, while Gemma 4 31B sits at 80th despite having more parameters. The gap illustrates how architecture and training choices matter more than raw parameter count for practical coding output. The result positions Qwen 3.8 27B as competitive with much larger frontier models.
/25 Aug 2026/Rreddit
A community investigator reverse-engineered how Claude Max x5 and Max x20 subscription plans compute usage after Anthropic declined to publish the methodology. The analysis identified a consistent set of point values that satisfy a "100x" principle across observed usage patterns. The findings allow Max subscribers to estimate remaining daily capacity more accurately than Anthropic's official guidance permits.
/25 Aug 2026/Rreddit
A Reddit post highlighted that Claude Enterprise administrators can pull complete chat histories for any employee on the account, including sessions conducted in incognito mode. The thread notes this is not prominently disclosed during onboarding and has prompted discussion about privacy expectations in enterprise AI deployments and the distinction between personal and managed work accounts.
/25 Aug 2026/Rreddit
Benchmark results show TielCoder, a 22 GB 4-bit quantized 35B Mixture-of-Experts model, matches Claude Opus 4.6 at medium effort on recent real-world coding tasks and surpasses Kimi K2. The model runs efficiently on constrained hardware and is positioned as a local alternative to frontier cloud models for coding workflows. The comparison used live coding problems rather than standard benchmark suites.
/25 Aug 2026/Rreddit
Thomson Reuters announced a proprietary frontier AI model trained on its curated legal, regulatory, tax, and news data assets. The model is designed for legal professionals and enterprise knowledge work rather than general use. TR joins a growing field of domain-specific players building frontier models on proprietary data rather than relying solely on third-party APIs.
/25 Aug 2026/YHN
OpenAI has announced a price reduction for GPT-5.6 Sol, its mid-tier frontier model, effective until at least November 21. The pricing change makes Sol more competitive against comparable Anthropic and Google offerings. Developers using the API through pay-as-you-go plans are eligible for the reduced rates without requiring a contract change.
/24 Aug 2026/YHN
A Financial Times report argues that Anthropic's most capable model is struggling to attract users as cheaper AI tools gain traction. The piece points to pricing and competition from lower-cost alternatives as key factors. The article reflects growing pressure on frontier model providers to justify premium pricing as mid-tier model quality has improved rapidly.
/24 Aug 2026/YHN
A developer hosted Kimi K3, Moonshot AI's 2.8 trillion parameter model, on 8 NVIDIA B300 GPUs via Modal, achieving 92 tokens per second at $190 per million tokens. Cold boot takes around 27 minutes to load the 1.56 TB model at a cost of roughly $56.79 per hour. The experiment shows frontier-scale inference is now accessible but remains expensive outside managed cloud services.
/24 Aug 2026/Rreddit
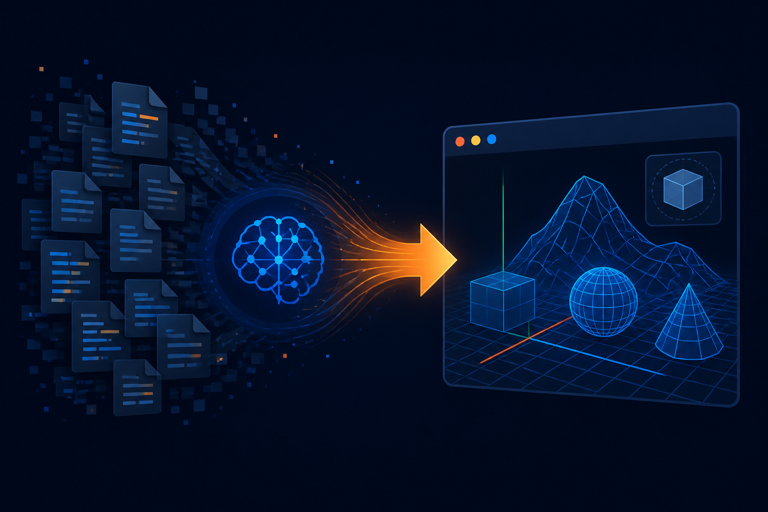
A developer tested Qwen 3.8 27B against Opus 5 on a hard coding task: porting a 39,000-line procedural shooter written in C to a single-file HTML/Three.js web app. Qwen completed the port and produced a working result. The comparison highlights Qwen 3.8 27B's competitive coding ability for large-scale refactoring work.
/24 Aug 2026/Rreddit
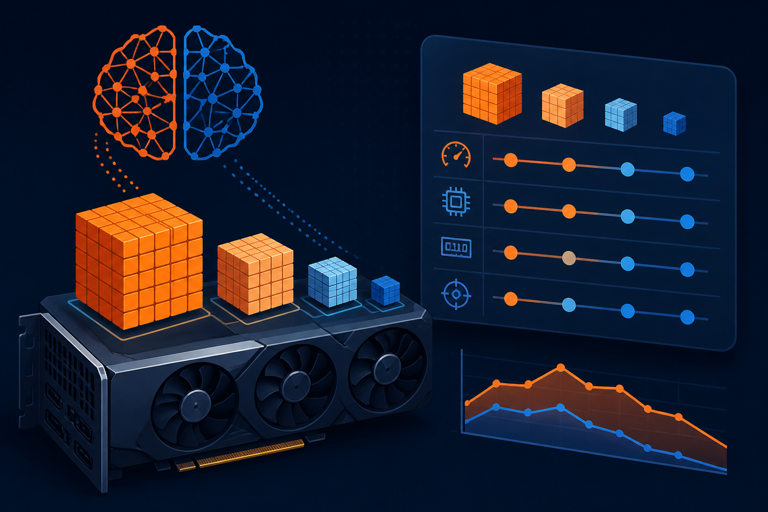
A team created Atomic Dynamic GGUF quantizations of Qwen 3.8 27B and compared their performance on a voxel island creation task using an RTX 6000. Results showed strong quality retention across quantization levels. The post shares the quantized files and methodology for running Qwen 3.8 27B locally on consumer hardware.
/24 Aug 2026/Rreddit
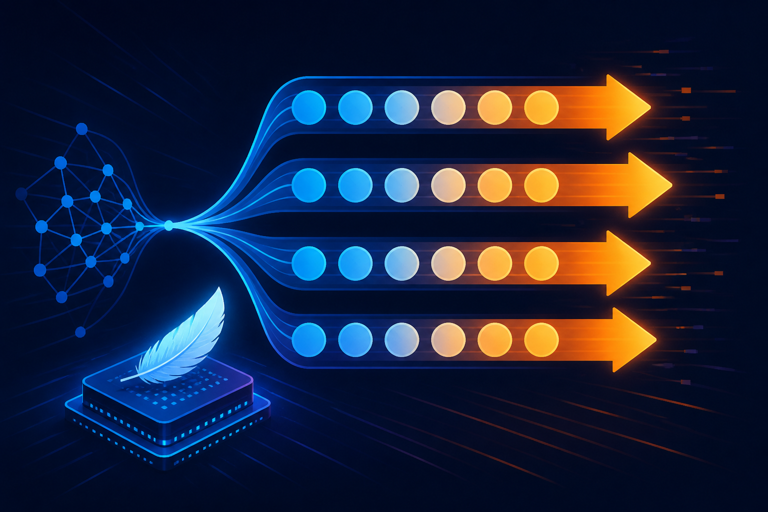
GLM-4.5-Air, a 106B mixture-of-experts model with only 12B active parameters, now supports Multi-Token Prediction in llama.cpp for a meaningful inference speed boost. The update makes it more practical for users who want a large MoE without requiring multiple high-end GPUs. MTP support is enabled via a configuration flag in the updated build.
/24 Aug 2026/Rreddit
A developer used Qwen 3.8 27B to reverse-engineer and document firmware for old hardware, a task that Claude Opus 4 had not been able to complete. Qwen 3.8 27B analyzed the firmware binary, generated documentation, and helped write compatibility shims. The post highlights the model's practical utility for embedded systems and legacy software preservation work.
/24 Aug 2026/Rreddit
Alibaba has previewed Swift-Image, a compact 6B-parameter unified model for text-to-image generation, single-image editing, and multi-image editing, described in a preprint on arXiv. If released as an open model, Swift-Image 6B would offer a lightweight alternative to larger image generation models for users with constrained hardware. No official release date has been announced.
/24 Aug 2026/Rreddit
A community discussion argues that Claude Opus 5 is not well-suited for extended coding sessions and delivers more value on discrete, high-judgment tasks. The thread explores where Opus 5 adds value versus Sonnet-tier models for day-to-day coding workflows. It reflects a broader pattern of users calibrating model choice by task type rather than defaulting to the most powerful option.
/24 Aug 2026/Rreddit
Liquid AI, known for fast Liquid Foundation Model (LFM) architectures and competitive small language models, is preparing a 100B parameter model release. This would be the company's largest model to date, following its track record of strong performance at smaller parameter counts.
/23 Aug 2026/Rreddit
A detailed setup guide documents running Qwen3.8-27B in NVFP4 quantization on a single RTX 5090 under vLLM, achieving 77 tokens/second at short context and 64.7 tokens/second at a real 262K token context window. The post provides reproducible configuration parameters for other 5090 owners targeting long-context local inference.
/23 Aug 2026/Rreddit
Palantir CEO Alex Karp publicly accused frontier AI labs of building products designed to create addictive dependency rather than genuine utility, drawing comparisons to drug addiction dynamics. The statement comes amid broader industry debate about engagement-driven business models at OpenAI, Anthropic, and other major labs.
/23 Aug 2026/YHN
OpenAI cut developer pricing for its frontier GPT-5.6 Sol model on 21 August 2026, effective for the next three months. Standard short-context pricing moves to $4 per 1M input tokens and $20 per 1M output tokens, down from $5 and $30, a 20% cut on input and about 33% on output. The reduction applies to the API and is rolling out across eligible plans for Codex credits and ChatGPT Work, while Pro, Plus and Business subscription pricing is unchanged. OpenAI cut its mid-tier GPT-5.6 Terra model by 20% and the lower-cost Luna model by 80% late last month.
/22 Aug 2026/YHN
/19 Aug 2026/GGitHub
System card data suggests 4.8 low effort matches 4.7 max on problem solving, while 4.8 medium burns more tokens than 4.7 high. Max mode scores slightly below x-high on SWE-bench, hinting overthinking degrades results.
/29 May 2026/r/r/ClaudeAI
Opus 4.8 arrives as a refined 4.7: fail-to-disclose rate drops from 19.7% to 3.7%, Dynamic Workflows bring parallel subagents to Claude Code as a research preview, and Fast mode offers 2.5x speed at a third of the cost.
/29 May 2026/r/r/ClaudeCode
Users report Opus 4.7 shows significantly degraded reasoning when prompted in other languages: shallow responses, missed context and lost chain-of-thought depth. Opus 4.6 does not show the issue.
/10 May 2026/r/r/ClaudeAI
Voicebox is a local-first TTS app: voice clone from seconds of audio, 23 languages, 5 TTS engines, DAW-style timeline for podcast/conversation production, 100% on-device. Free alternative to ElevenLabs. Community: wor...
/20 Apr 2026/r/r/StartupMind
A meta-analysis of 110 release-day threads and 2,187 comments: Opus 4.7 is better at planning and orchestration, but token burn is heavy (one user hit 1.06B tokens in a day) and non-max effort brings laziness and.
/19 Apr 2026/r/r/ClaudeCode
GLM-OCR handles complex tables, code-heavy documents, seals and multilingual layouts with a two-stage layout-then-recognition pipeline. At 0.9B parameters it runs locally via Ollama, vLLM or SGLang.
/17 Apr 2026/r/r/unknown
Pingu Unchained is a 120B uncensored model built for adversarial security testing: no content filters, 75+ security tool integrations via MCP, full token logging for accountability, and identity verification required.
/16 Apr 2026/r/r/unknown
LLaMA-Factory provides a unified web UI + CLI for fine-tuning LLMs and VLMs without writing custom training code. Supports LLaMA, Mistral, Qwen, DeepSeek, Gemma, Phi, Yi, and 90+ others. Positioned as a no-code altern...
/14 Apr 2026/r/r/LovingOpenSourceAI
Cognition released SWE-2, a new software engineering model it claims rivals Fable 5.1 and GPT-Astra on coding benchmarks. The model builds on the company's prior work on Devin and focuses on real-world engineering tasks beyond standard evaluation suites.
/Iingest
A researcher reported that DeepSeek and Moonshot AI were routing customer conversations to Claude's API without disclosing this to users. The claim raises questions about transparency in AI product stacks and undisclosed third-party model use.
/Iingest
DeepSeek released V4-1 Flash, a multimodal Mixture-of-Experts model with 552 billion backbone parameters and support for up to one million tokens of context. The release follows the earlier V4 Pro and continues DeepSeek's rapid model shipping pace.
/Rreddit
An Anthropic researcher who publicly raised safety concerns reportedly gave up their vested equity in order to leave the company, an unusual step that underscores the tension between financial incentives and dissent in AI labs. The case follows earlier public criticism of Anthropic's direction.
/Rreddit
OpenUI released OUI-1, a model fine-tuned on DiffusionGemma using OpenUI-Lang, a custom domain-specific language for UI generation. The model generates bespoke interface components rather than raw HTML, targeting design-to-code workflows.
/Rreddit
Muse-glimmer-30B ranks competitively against much larger frontier models on EQ-Bench Creative Writing and Hemingway-bench. Users running it locally report strong narrative quality relative to its 30 billion parameter size.
/Rreddit
 AIFIRST