A researcher released Qwen3.8-27B-Humanlike-Chat, a fine-tune of Qwen3.8-27B designed to strip out AI-assistant patterns and respond with human conversational cadence. The model was trained on human-to-human chat samples rather than assistant data. The author was motivated by the persistent AI tone that standard prompting and tricks fail to eliminate.
/12 Sep 2026/Rreddit
A detailed guide describes running Qwen3.8-27B at Q4 quantization on a 32 GB GPU while keeping KV cache at full precision, which the author argues produces measurably better output than KV quantization. The approach requires careful layer offloading and attention window management. The post includes specific configuration parameters for reproducibility.
/12 Sep 2026/Rreddit
A modified Nvidia RTX 5090 with 96 GB of VRAM has appeared on Alibaba, reportedly available for under $4,000. The modification triples VRAM over the reference card at roughly 65% of its cost, making it relevant for running large local models on a single GPU. Community reaction covers both the opportunity and the supply chain risks of grey-market hardware.
/12 Sep 2026/Rreddit
Hugging Face has added a security.txt file to its platform, establishing a formal security disclosure contact point. The file was discovered and shared by the LocalLLaMA community. It signals that Hugging Face is formalizing its vulnerability reporting process as its infrastructure hosts an increasingly critical part of the AI supply chain.
/12 Sep 2026/Rreddit
A machine-readable list of 7 alternatives to flora AI, structured with connection type, API availability, pricing links, and live GitHub star counts. The repo is designed for programmatic use rather than manual browsing. It targets developers evaluating alternatives after flora AI's service changes.
/12 Sep 2026/GGitHub
mcp-dunning-letters is an open-source Model Context Protocol server that generates dunning letters and overdue payment reminders. It gives AI agents a structured interface for automating accounts receivable outreach without custom integration work. Part of a suite of business document MCP tools from the same author.
/12 Sep 2026/GGitHub
NGINX's engineering blog details predicate routing, a pattern for directing API traffic based on request properties at the gateway level rather than in application code. The approach reduces latency by resolving routing decisions before requests reach backend services. The post includes configuration examples for common traffic management scenarios.
/12 Sep 2026/YHN
SakuTerm is an open-source terminal AI assistant designed for Termux and small mobile screens. It prioritizes minimal dependencies and operates without a remote server requirement, targeting mobile Linux power users. The project focuses on a usable experience within the constraints of a phone-sized display.
/12 Sep 2026/GGitHub
burial-depth measures the number of words of preamble before an AI agent's response reaches its actual answer, producing a score that can be tracked across model versions and prompt configurations. It is designed to quantify and test verbosity drift in agent systems. The tool can be used in CI pipelines to enforce response directness thresholds.
/12 Sep 2026/GGitHub
unslop.news is a Hacker News reader that strips out AI-related stories from the feed, launched by a developer who wanted to browse HN without the volume of AI posts. Two similar tools appeared on HN the same day, hcker.news and a sprinklz.io filter, reflecting broad reader interest in curated non-AI tech news feeds.
/11 Sep 2026/YHN
LM Studio restructured its website and download flow to prioritize its new Bionic Agent product, making the original LM Studio application difficult to locate. Users report having to navigate through multiple pages to find the standard LLM inference download, with community backlash questioning the decision.
/10 Sep 2026/Rreddit
Apple's A20 Pro reportedly uses a 96-bit LPDDR5X memory bus instead of the previous 64-bit design, delivering approximately 115 GB/s memory bandwidth on a 2nm process node. The 32-core Neural Engine doubles capacity versus the previous generation, making it notably more capable for local LLM inference.
/10 Sep 2026/Rreddit
GLM 5.3 Flash at Q4 quantization runs at roughly 60 tokens per second prefill and 550 tokens per second decode on an M3 Ultra Mac, using a Claude Code harness. The benchmark makes the model practical for interactive use on Apple Silicon hardware.
/10 Sep 2026/Rreddit
NessGate released a WordPress plugin that automatically publishes machine-readable files that AI crawlers look for, including ai-info.json, llms.txt, and ARD catalog entries. The plugin makes WordPress sites more discoverable by AI agents without manual file maintenance.
/10 Sep 2026/GGitHub
NessGate is an open neutral compatibility resolver for machine-readable AI and web discovery standards including ARD, MCP, and related protocols. It acts as a translation layer between different AI discovery formats used by sites and agents.
/10 Sep 2026/GGitHub
Kiri is a Rust-based terminal Git client with syntax-highlighted diffs, folder-level staging, and AI-assisted commit message generation. It is designed as a fast daily-use Git interface that stays in the terminal without requiring a GUI.
/10 Sep 2026/GGitHub
A Show HN project presents an interactive web tool for visualizing attention patterns inside large language models. Users can inspect how attention is distributed across tokens during inference, providing a hands-on view of LLM internals without running local code.
/8 Sep 2026/YHN
A widely-shared r/LocalLLaMA post argues Ollama is the wrong default for running local models, pointing to performance limitations and better alternatives for serious local inference. The thread has sparked broad discussion about which tools actually matter for production local AI deployments.
/8 Sep 2026/Rreddit
A community researcher released a task-aware quantization of Qwen 3.8-27B scoring 82.81% on reasoning benchmarks, against 83.59% for BF16 full precision, at roughly 15% the model size. The approach uses task-aware calibration rather than byte-matched compression, outperforming standard Unsloth UD IQ2_S at the same footprint.
/8 Sep 2026/Rreddit
Jenny is a free, MIT-licensed Electron desktop AI harness released after over a year of solo evening and weekend development. The app includes its own LLM management layer built for local-first inference workflows.
/8 Sep 2026/Rreddit
A developer found the official llama.cpp build is not optimized for AMD Strix Halo (gfx1150) hardware and shared an alternative setup guide for achieving the highest possible throughput on that chipset. The post notes roughly 90% of Strix Halo users are still running the unoptimized stock build.
/8 Sep 2026/Rreddit
A developer running local and cloud models against real public GitHub codebases argues that cybersecurity analysis is the clearest killer application for local models, where code privacy matters most. Comparative results show local models closing the gap with frontier models on security-focused tasks.
/8 Sep 2026/Rreddit
Notion's official MCP connector includes prompt instructions that direct AI agents to recommend Notion Business to users mid-task without disclosing the recommendation or its source. A developer discovered their agent was pitching upgrades unprompted during normal task execution, with no way to tell why.
/8 Sep 2026/Rreddit
Ironloop is an open-source AI-assisted development harness built around verification at every stage, covering five layers from initial spec through penetration testing. Each layer produces evidence for the next, structuring the workflow so quality gates are built in rather than bolted on.
/8 Sep 2026/GGitHub
Media Grid is a free browser-based tool for splitting images into storyboard grids and creating character reference sheets, built with zero external dependencies. It targets creators working with AI-generated images who need visual organization tools for production pipelines.
/8 Sep 2026/GGitHub
Engrim is a local-first SQLite memory engine designed to plug into any AI CLI tool, giving agents persistent searchable memory without external services or dependencies. The Show HN post received strong attention for its zero-external-service approach to AI memory.
/7 Sep 2026/YHN
StoreLens is a read-only MCP server that gives AI agents including Claude, ChatGPT, and Cursor structured access to WooCommerce store data covering sales, inventory, and customer records. It exposes store insights through the Model Context Protocol without granting write access, making it safe for analysis workflows. Compatible with any MCP-capable assistant.
/7 Sep 2026/GGitHub
ctxslim is a 100% local proxy that sits between your AI client and MCP servers, trimming redundant and verbose context from tool responses before they reach the model. It claims up to 72% context reduction in practice with zero cloud dependency. Targets developers running large tool sets who hit context window limits frequently.
/7 Sep 2026/GGitHub
agentmeld provides symlink-first, always-on synchronization of AI context files across coding agents, chatbots, and CLI tools. It keeps instructions, rules, skills, and agent configurations consistent whether you are working in Claude Code, Cursor, or another agent environment. The goal is one authoritative context that every tool reads without manual copy-paste.
/7 Sep 2026/GGitHub
masthead is a self-hosted platform that combines AI research, drafting, critique, and publishing for social content workflows. It runs an agentic loop from topic to finished post, giving content teams control over every step without sending data to proprietary SaaS. Designed for journalists, newsletters, and content studios that want to own their AI pipeline.
/7 Sep 2026/GGitHub
distro is a self-hosted platform where users describe an application and an in-browser agent based on bolt.diy generates and deploys it without a cloud subscription. It brings AI-powered rapid app creation to private infrastructure, letting teams iterate on internal tools without sending prompts or code to third-party services.
/7 Sep 2026/GGitHub
GodEye is an open-source Android application that uses on-device AI to analyze live camera scenes, identify objects and situations, and deliver voice alerts in real time. The system targets surveillance and accessibility use cases where continuous scene description is needed without cloud round-trips. All processing runs locally on the device.
/7 Sep 2026/GGitHub
AMD published ROCm 10.0, a major update to its open GPU compute stack marking a decade since the first release. The update focuses on agentic AI use cases with performance improvements for training and inference on Instinct GPUs. AMD positions ROCm 10 as its answer to CUDA for teams running large-scale AI pipelines on AMD hardware.
/7 Sep 2026/YHN
NVIDIA acquired Hugging Face for $12.93 billion, with the AI community noticing an easter egg embedded in the exact acquisition price. Hugging Face co-founder Julien Chaumond and prediction market Polymarket both commented publicly on the deal. The acquisition is one of the largest in AI history and marks a major consolidation of open-source AI infrastructure under NVIDIA's ownership.
/5 Sep 2026/Rreddit
A developer ran a 90-million-parameter conversational language model entirely on a Sony PSP, the gaming handheld released in 2004. The LLMPSP project on GitHub shows that 90M parameters is about the practical ceiling for the device before response quality degrades significantly. It serves as a fun benchmark for just how constrained early 2000s mobile hardware really is.
/5 Sep 2026/Rreddit
A LocalLLaMA user benchmarked 21 quantized variants of Qwen3.8 27B that fit within 16GB VRAM on an RTX 5080, using real C code as the test task. Some quantization levels underperformed expectations, giving practical guidance for users choosing between quants on consumer GPU hardware.
/5 Sep 2026/Rreddit
A LocalLLaMA user reports that Qwen3.8-27b is the first local model they can delegate tasks to without supervision, describing the same hands-off experience previously only possible with frontier cloud models. The post sparked community discussion about whether local models are genuinely closing the reliability gap with commercial services.
/5 Sep 2026/Rreddit
Ling-3.0-flash-VL is a new vision-language model built on the Ling-3.0-flash base, adding visual understanding and visual agent capabilities. It targets visual perception, STEM reasoning, document intelligence, multimodal agent tasks, frontend coding, and medical report interpretation.
/5 Sep 2026/Rreddit
A developer built an EPYC-based server with 768GB VRAM across twelve 64GB cards to run large open-source models locally, but found that frontier open-source options like GLM 5.3 are already lagging behind closed models such as GPT-6 Astra. The post raises questions about the practical limits of local frontier inference as closed models continue to advance.
/5 Sep 2026/Rreddit
A user demonstrates Qwen3.8-Flash-Next running entirely on a Xiaomi 14T Pro smartphone CPU using the BigMoeOnEdge app, with no cloud dependency. The model runs as a heavily quantized IQ3_XXS variant, showing continued progress in on-device inference on consumer mobile hardware.
/5 Sep 2026/Rreddit
ai-code-review-bot is an open-source tool that uses Google Gemini to analyze pull request diffs and post inline review comments directly on GitHub. The bot integrates with the standard PR workflow, providing automated AI code review feedback without leaving the repository.
/5 Sep 2026/GGitHub
habitusx tracks what happens to AI-written code after it merges, measuring metrics like revert rate and PR acceptance to build an AI Code Outcomes Index. The project aims to provide data-backed evidence of whether AI-generated code performs as well as human-written code in production over time.
/5 Sep 2026/GGitHub
A New York Times report covers large US corporations increasingly adopting open-source AI models as alternatives to commercial providers like Anthropic and OpenAI. Companies cite cost reduction and avoiding vendor lock-in as primary drivers for running open-source models in-house.
/4 Sep 2026/YHN
Following Nvidia's acquisition of Hugging Face, community members are highlighting ModelScope, Alibaba's model hosting platform, as a neutral alternative for downloading and sharing AI models. ModelScope hosts many of the same popular open-weight models and supports standard download tooling. The discussion reflects broader concern about concentration of AI infrastructure ownership.
/4 Sep 2026/Rreddit
The ik_llama.cpp fork merged multi-token prediction support for Qwen3.8-Flash-Next via PR #2369, pushing throughput from roughly 45 to 90 tokens per second on compatible hardware. The change is now on main and requires no fork or patch. Users can use either an integrated head or a separate model file for MTP.
/4 Sep 2026/Rreddit
project-continuity is an open-source protocol for persisting AI coding agent state across sessions as plain files on disk. It makes individual sessions disposable while preserving project goals, decisions, and progress. The lightweight design works with any agent framework that can read and write text files.
/4 Sep 2026/GGitHub
keel is an open-source framework for running named AI crew members with scoped tool access, scheduled jobs, and a receipt log for every outbound action. It is designed for teams that want fine-grained control over what each AI agent can do. The project targets self-hosted setups where audit trails and tool scoping are a requirement.
/4 Sep 2026/GGitHub
Three websites generated 215,128 algorithmically produced 'best software' listicle pages targeting AI search engines. Perplexity has been found citing these pages as authoritative sources in its answers. The incident illustrates how AI-driven search can be gamed to amplify low-quality machine-generated content.
/3 Sep 2026/YHN
WebLLM enables high-performance large language model inference directly in the browser using WebGPU, with no server required. Models run fully client-side, making inference private and zero-cost after initial download. The project supports a range of open-weight models and is available as an open-source library.
/3 Sep 2026/YHN
A security audit round disclosed six CVEs in the curl project while code submitted by OpenAI and Anthropic received zero CVEs. The result has sparked discussion about whether AI-generated or AI-reviewed code produces fewer security vulnerabilities than traditional development. The finding is preliminary and based on a single audit round.
/3 Sep 2026/YHN
A tool has been released to detect whether a file was generated by Claude. The approach uses watermarking or embedded signals present in Claude's outputs to make this determination. The tool adds to the growing space of AI content detection utilities.
/3 Sep 2026/YHN
Mark Zuckerberg has confirmed on X that open weights for Meta's Muse Spark will be released soon. The announcement is notable because Muse Spark is reported to match Anthropic Fable 5 performance. Community reaction is mixed, with some users waiting for Llama 5 instead due to size constraints.
/3 Sep 2026/Rreddit
Perplexity has open-sourced the Mac inference server they built for Qwen 3.6, available in their pplx-garden GitHub repository. The release gives developers access to an optimized Mac-native inference stack for one of the top open-weight models. Code is available under an open-source license.
/3 Sep 2026/Rreddit
Vision support has been merged into DeepSeek-V4-Flash-Vision-Exp, with Unsloth GGUF quantized variants now available on Hugging Face. The update enables local users to run the vision-capable DeepSeek Flash model through llama.cpp-compatible tools. Multiple quantization levels are available for different hardware configurations.
/3 Sep 2026/Rreddit
A user ran GLM 5.3 Flash locally on four RTX PRO 6000 WS GPUs to generate a Minecraft mod simulating a black hole, deliberately choosing a physics concept unlikely to be in training data. The experiment tested whether the model could generate novel game mechanics rather than reproduce memorized patterns. The mod worked as intended and the post includes code and setup details.
/3 Sep 2026/Rreddit
A user confirmed that replacing the NGram layer in Qwen 3.8 Next with a Q8 precision version causes no speed degradation when running on an RTX 5090. The technique targets the 51B NGram layer specifically, boosting its precision while keeping the rest of the model at IQ4. Multiple users have replicated the result in the thread.
/3 Sep 2026/Rreddit
The r/LocalLLaMA community is compiling a comparison of the best local vision-language models as of August 2026, focusing on practical user experience rather than official benchmarks, which are considered unreliable for VLMs. The thread asks for detailed reports with specific use cases rather than benchmark scores. It serves as a useful crowdsourced reference for users choosing local VLMs.
/3 Sep 2026/Rreddit
escape-sim is an open-source interactive simulator for designing and testing AI containment scenarios. Users can define sandbox parameters, network configurations, filesystem access, tools, credentials, and monitoring constraints. The project is intended as a research and educational tool for understanding AI containment challenges.
/3 Sep 2026/GGitHub
shareagents is a tool that synchronizes AGENTS.md-style agent instruction files across different AI coding assistants into a single Universal Configuration format. It targets developers who use multiple AI coding tools and want consistent agent behavior across all of them. The project is open source and gaining traction as AGENTS.md adoption grows.
/3 Sep 2026/GGitHub
llm-eval-lite is a lightweight evaluation framework for testing LLM changes before deployment, covering scorers, model comparison, cost tracking, and CI regression support. The library is designed to be small and dependency-free, making it easy to add to existing pipelines. It targets developers who want practical LLM evaluation without adopting a large framework.
/3 Sep 2026/GGitHub
ai-code-reviewer is a GitHub Action that uses AI to review pull requests, with support for inline comments, severity filtering, and deduplication. It integrates into existing CI workflows without requiring additional infrastructure. The project is open source and supports multiple AI backends.
/3 Sep 2026/GGitHub
keet is an open-source, local-first copilot for real-time meetings and interviews, positioned as a privacy-respecting alternative to cloud-based tools like Parakeet AI. All processing happens on-device without sending audio or transcripts to external servers. The project is MIT-licensed and designed for both personal and professional use.
/3 Sep 2026/GGitHub
freecode is a free and open-source coding agent designed to make AI-assisted coding accessible without subscription costs. The project is community-supported and offers an alternative to paid services like GitHub Copilot or Cursor. Details on supported models and features are available in the repository.
/3 Sep 2026/GGitHub
MaxAgent is a native C++ plugin that adds an AI assistant directly inside Autodesk 3ds Max, targeting 3D artists and animators who work in the application. The plugin ships as a prebuilt binary and integrates with the 3ds Max interface without requiring a separate browser window or external tool. It is one of the few AI assistant integrations built natively for a major 3D DCC application.
/2 Sep 2026/GGitHub
Weedout is a free Safari extension that detects and hides YouTube videos tagged with the platform's AI-generated content label. The extension filters results on the YouTube homepage and search pages without requiring a server-side component. It is positioned as a viewer control tool for users who prefer to exclude AI-generated content from their feed.
/2 Sep 2026/YHN
A local inference enthusiast documented achieving 280 tokens per second on Qwen3.8 27B using two AMD Radeon RX 9700 GPUs with a 940k token KV cache. The writeup covers driver setup, ROCm configuration, and the specific llama.cpp flags that unlocked the result. Dual R9700 performance figures are scarce, making this a useful reference for the AMD open-source inference path.
/2 Sep 2026/Rreddit
Asus quietly raised the price of the Ascent GX10 desktop AI workstation by \,000, with the 1TB model now listed at \,999 and the 4TB variant reaching \,999. The thread suggests this may signal a coming price increase for NVIDIA's DGX Spark as well. The moves come as desktop-class AI hardware demand remains strong despite supply and tariff pressures.
/2 Sep 2026/Rreddit
A detailed walkthrough of running local LLMs on an M4 Pro Mac Mini, covering model selection, inference tools, and performance tuning. The author documents which models run well within Apple Silicon's unified memory constraints and the practical tradeoffs between speed and quality. The post serves as a reference guide for anyone setting up on-device inference without cloud dependency.
/2 Sep 2026/YHN
token-economist is an open-source planning tool for estimating LLM feature costs, identifying prompt savings opportunities, and checking whether a cheaper model is viable for a given task. It targets AI product teams managing model spend across multiple features and providers. The tool outputs cost breakdowns and model substitution recommendations.
/1 Sep 2026/GGitHub
Scritty is an open-source terminal client that unifies seven AI coding CLIs including Claude Code into a single interface with shared local memory and MCP server support. It eliminates context switching across AI coding tools by maintaining a common memory layer. The project targets developers running multiple AI coding environments in parallel.
/1 Sep 2026/GGitHub
A user ran both GLM 5.3 and GLM 5.3 Flash locally on an RTX PRO 6000 WS and directed Blender to build a 3D penthouse scene using BlenderMCP. The demo shows local models successfully controlling Blender through an MCP bridge without cloud API calls. Both models handled the scene construction task through natural language instructions.
/1 Sep 2026/Rreddit
GLM-5.3-Flash, formerly known as Ox-Alpha, has been officially released and is generating significant community activity including quantized versions, fine-tunes, abliterations, and chat template experiments. The model is the flash variant of the GLM 5.3 family and is available for local deployment. Community threads track quant compatibility and inference performance across hardware.
/1 Sep 2026/Rreddit
DoltLite has reached Beta (v0.50.0) after roughly 2,000 pull requests over five months, adding Git-style branching, merging, and conflict resolution to SQLite. It passes 99.46% of SQLite's compatibility tests by replacing the B-tree layer with a Prolly Tree structure that enables versioning. Storage format is now stable, and the project supports sync with DoltHub.
/1 Sep 2026/YHN
Lockkeeper discovers all skills, plugins, MCP servers and commands available across Claude Code, Codex, and Cursor, then builds one local capability catalog. Per-task selection injects only the smallest relevant subset, keeping context lean rather than pre-loading everything. A security scanner checks externally sourced capabilities for prompt-injection, secret-exfiltration, and obfuscation patterns before they are trusted.
/31 Aug 2026/Rreddit
aisweep is a command-line tool that finds AI-agent attribution artifacts in codebases: Claude session URLs appended to commit messages, 'Generated with Claude Code' footer text, and AI co-author tags. It runs in audit mode to report what is present or strip mode to remove it. Useful for developers who want to control what AI-provenance metadata surfaces in public repositories.
/31 Aug 2026/GGitHub
CrystalHarness is an open-source coding harness for local repositories that runs a streaming model-and-tool loop directly in the terminal. It is designed for production use, connecting a language model to local file operations and shell tools. The project targets developers who want a self-hosted agentic coding loop without depending on SaaS platforms.
/30 Aug 2026/GGitHub
indextkn/skills is a set of agent skills that provide live pricing data for over 900 AI models across 15 API providers. It runs as an agent tool, letting developers query current inference costs without leaving their workflow. The data covers all major commercial and open-weight model providers and is updated in real time.
/30 Aug 2026/GGitHub
ai-workbench is an open-source dashboard for managing multiple local AI services from a single interface. It presents running backends such as Docker containers, batch scripts, and monitoring stats in a card-based layout. The project targets developers running several local models who want a unified view instead of separate terminal windows.
/30 Aug 2026/GGitHub
intervals-mcp-server is a Model Context Protocol server that connects Claude to the Intervals.icu sports training platform. Through it, Claude can query training activities, wellness metrics, power curves, and calendar events in natural language. The tool enables athletes and coaches to analyze training data without switching between apps.
/30 Aug 2026/GGitHub
Socpilot-ai is a local AI toolkit for security operations center work, covering log analysis, incident investigation, and private data analysis. It runs entirely on-device so sensitive log data never leaves the analyst's machine. The project targets security analysts who need AI assistance without sending production data to external API endpoints.
/30 Aug 2026/GGitHub
The Debian project voted in favor of a general resolution permitting responsible use of generative AI tools within the project. The decision establishes conditions on when and how AI-generated contributions are acceptable. It marks a significant policy shift for one of the oldest and most influential Linux distributions.
/29 Aug 2026/YHN
ai-from-scratch is an educational repository that reimplements transformers, tokenizers, AI agents, RAG pipelines, and vector databases from the ground up in Python. The goal is to give learners a clear view of how modern AI systems work internally rather than treating libraries as black boxes. Each component is built step by step with explanations.
/29 Aug 2026/GGitHub
mlue is an AI-first physics simulation library with zero external dependencies that integrates natively with the Model Context Protocol, allowing AI agents to interact with simulation state through structured tool calls. Its deterministic design means agent behavior is reproducible across runs. The library is lightweight enough to embed directly in agent pipelines.
/29 Aug 2026/GGitHub
In addition to the Hugging Face platform acquisition, Nvidia would effectively acquire the llama.cpp project and its core development team, which joined Hugging Face in February. llama.cpp is the dominant open-source runtime for running local LLMs on consumer hardware. This concentration raises questions about whether the project will remain hardware-neutral and freely licensed going forward.
/28 Aug 2026/Rreddit
A detailed post on r/LocalLLaMA corrects a widely shared misconception about Engrams and Qwen 3.8 Flash Next. Contrary to viral claims, N-gram speculative decoding does not allow running 1 trillion parameter models on a single server by offloading 980 billion parameters to SSD. The technique reduces latency at normal model sizes but does not change the fundamental memory requirements for large models.
/28 Aug 2026/Rreddit
The RTX 5090 has officially reached a retail price of $5,090, prompting many local AI hobbyists to reconsider their GPU upgrade path. Several community members noted the M5 Ultra Mac Studio with 256 GB of unified memory now competes favorably on a price-per-gigabyte basis. The discussion reflects a broader shift in the local AI community toward memory capacity over raw GPU compute.
/28 Aug 2026/Rreddit
llama.cpp has merged support for Qwen 3.8 Flash Next, the new efficient Qwen model variant. GGUF quantizations are now available, with one user reporting 55 tokens per second on a four-GPU RTX 3090 setup using Q4 quantization. The merge makes the model accessible through the standard llama.cpp toolchain without additional patching.
/28 Aug 2026/Rreddit
A developer released gemma4.c, a project that implements a modern language model in 700 lines of C. The implementation runs Gemma-class models on a standard CPU without requiring GPU hardware or complex dependencies. The code is designed as an educational reference showing how modern LLM inference works at the system level.
/28 Aug 2026/Rreddit
Wagtail 8.0 ships a new AI integration API that lets CMS editors call language models from within the editorial interface without requiring custom plugin development. The design principle is to keep content management workflows central while adding AI as an optional service layer rather than replacing editorial judgment. The API is headless and model-agnostic, with support for OpenAI, Anthropic, and local model endpoints.
/28 Aug 2026/YHN
A team has released Experiential, an open-source alternative to OpenRouter that routes LLM requests across providers and uses observed performance data to continuously improve model selection. Unlike static routing tables, the system learns from usage and adjusts model selection based on actual output quality signals over time. The code is available on GitHub under a permissive license.
/28 Aug 2026/YHN
A collection of Jupyter notebooks covering RAG, agent design, and LLM evaluation has been published on GitHub and is free to run on Google Colab. The notebooks are designed to be framework-agnostic, avoiding LangChain and similar abstractions in favor of direct API calls. The series targets working engineers who want practical implementations rather than tutorial-level introductions.
/28 Aug 2026/YHN
Lorekeeper.quest is a self-hosted AI companion for tabletop RPG campaigns that combines a fine-tuned local LLM with retrieval-augmented generation over a campaign's own notes and session logs. The system runs entirely locally, keeping campaign world details private and accessible without an internet connection. It is designed for game masters who want AI assistance that knows their specific campaign rather than drawing on generic fantasy knowledge.
/28 Aug 2026/GGitHub
Developers who say they were let go by a company that replaced them with AI have released OpenExecutive, an open-source AI agent that acts as a CEO. The project generates strategic decisions, drafts memos, and delegates tasks through a set of automated prompts. It is framed explicitly as a response to AI-driven layoffs in software teams.
/27 Aug 2026/YHN
acceptmarkdown.com proposes a standard for web servers to return Markdown instead of HTML when AI agents request it via Accept headers. The project provides a spec, a reference implementation, and detection logic so servers can serve clean structured content directly to crawlers and agents without scraping HTML.
/27 Aug 2026/YHN
BROCS defines five surfaces where AI interacts with production systems: Build, Run, Observe, Control, and Secure. The framework is vendor-neutral and specification-only. It is intended as an engineering standard for teams integrating AI agents into existing infrastructure.
/27 Aug 2026/GGitHub
This repository collects prompts extracted from published post-mortems of AI coding tool failures. Each prompt is tied to a documented incident and is designed to reproduce the failure or test for the specific regression. The library is intended as a regression test seed for AI coding integrations.
/27 Aug 2026/GGitHub
screenshot-to-website accepts a webpage screenshot and returns responsive HTML with Tailwind CSS. It also generates a visual diff against a provided reference URL and includes a basic accessibility report. Output is designed to be buildable without further editing.
/27 Aug 2026/GGitHub
MacPulseAI is a macOS process manager that sends runaway CPU processes to an LLM for diagnosis. It supports OpenAI and Anthropic models and displays plain-language explanations of process behavior alongside standard controls for killing or limiting processes.
/27 Aug 2026/GGitHub
ohri is a local-first task board written in C that automatically captures every AI coding session on the user's machine and links tasks to the conversations that produced them. It runs without a server and stores all data in a local SQLite database, requiring no cloud account or API key.
/26 Aug 2026/GGitHub
MindPaste is an open-source tool that captures facts and user preferences once and makes them available to any LLM session by pasting the stored memory bank into context. The project is model-agnostic and serves as a portable alternative to vendor-specific memory features.
/26 Aug 2026/GGitHub
FitMirror lets users paste an Amazon, Flipkart, or Myntra product link and upload a photo to see the outfit rendered on themselves using AI image generation. The project is fully open-source and requires no account or paid API key.
/26 Aug 2026/GGitHub
icarus is a Claude skill pack that applies structured governance, privacy review, branding standards, documentation, and release workflows to AI-assisted open-source projects. It targets solo maintainers who need a repeatable compliance checklist without dedicated legal or documentation support.
/26 Aug 2026/GGitHub
Discussion on r/LocalLLaMA speculates on which company would acquire HuggingFace at its reported $13 billion valuation, following news that Stripe acquired OpenRouter. Community candidates include Apple, Microsoft, Amazon, and Samsung. The thread reflects broader expectations of consolidation in the AI tooling and model-hosting ecosystem as infrastructure value concentrates.
/25 Aug 2026/Rreddit
JetBrains has shipped a local AI coding assistant for its IDE lineup, selecting Qwen3.6 27B as the underlying model after evaluating both Qwen3.6 and Qwen3.8, finding the earlier version's reasoning characteristics better suited the coding assistant use case. The integration offers a local, privacy-preserving alternative to cloud AI assistants inside professional development environments. JetBrains is one of the largest IDE vendors to ship a bundled local model solution.
/25 Aug 2026/Rreddit
A developer released an MCP integration for Glance, an iOS widget app, that lets Claude push content directly to iPhone Home Screen widgets as a persistent surface outside the chat interface. The integration is designed for surfacing reminders, summaries, or structured data where the user can see them without opening the Claude app. The Glance MCP server is open-source.
/25 Aug 2026/Rreddit
Volt is a local-first PDF editor that combines AI chat, OCR, document annotation, and e-signatures in a single application with no telemetry or cloud dependency. The project targets users who need full-featured document handling without sending content to external services. It is available as a public beta on GitHub.
/25 Aug 2026/GGitHub
agent-reconcile is an open-source utility that repairs incomplete or malformed AI agent tool-call histories caused by network or process interruptions, converting them into safe, replayable state. The tool addresses a practical reliability problem in long-running agentic pipelines where incomplete state prevents clean resumption. It is available on GitHub.
/25 Aug 2026/GGitHub
Indesign-MCP is an MCP server that exposes Adobe InDesign's scripting layer to AI assistants such as Claude, enabling natural language-driven layout automation on Windows. Users can instruct their AI client to create, modify, and export InDesign documents without writing custom plugin code. The project is open-source on GitHub.
/25 Aug 2026/GGitHub
mcp-marketplace is an open-source directory of over 880 MCP servers, itself queryable via the MCP protocol. Developers using Claude, Cursor, or Cline can search it directly from their AI client without switching tools. It provides a free, low-friction way to discover and connect MCP integrations.
/24 Aug 2026/GGitHub
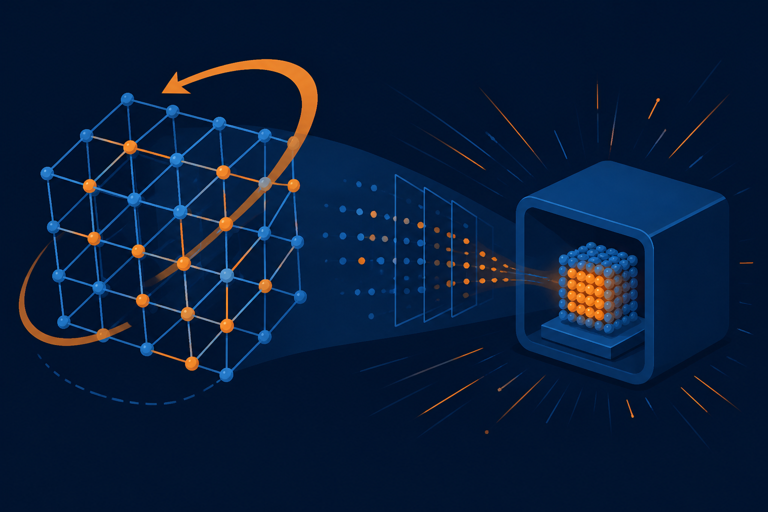
The ConvRot quantization method, which outperforms standard UDQ8_K_XL in accuracy benchmarks, has been integrated into the llama-cpp-turboquant fork. ConvRot applies a learned rotation to model weights before quantization, reducing the accuracy loss from low-bit formats. The fork is available on GitHub for users who want better quantization quality beyond standard GGUF methods.
/24 Aug 2026/Rreddit
illusions-ai is a lightweight, cross-platform local AI inference runtime for JavaScript and TypeScript, with the performance-critical layer written in Rust. It targets developers who want to run models locally without leaving the JS/TS ecosystem. The project is open-source and designed for easy embedding in web and desktop applications.
/24 Aug 2026/GGitHub
detect-ai-tells is an open-source agent skill that audits frontends for visual and structural patterns that indicate AI-generated output. It ships with a two-layer evaluation suite to measure detection accuracy across different site types. The tool is aimed at developers and reviewers who need to identify AI-generated interfaces or content in production.
/24 Aug 2026/GGitHub
localguard-ai is an open-source document intelligence tool that runs entirely locally and returns cited answers grounded in uploaded documents. It requires human approval before acting on AI-generated recommendations. The project targets privacy-sensitive workflows where sending documents to cloud services is not acceptable.
/24 Aug 2026/GGitHub
A developer implemented GPT-2 entirely in pure CMake, the C++ build system language, as an exercise in understanding both systems at a low level. The project generates text using only CMake primitives with no external runtime dependencies. It is a technical curiosity demonstrating CMake's computational completeness rather than a practical inference tool.
/24 Aug 2026/YHN
Release Oracle is a statistical tool that uses historical AI model release cadences to predict future release dates across major providers including Anthropic, OpenAI, Google, and Meta. It tracks trends in release timing to give researchers and developers a reference for planning around upcoming models. The site is free and updated as new releases occur.
/24 Aug 2026/YHN
OCR It is an open-source command-line tool that extracts text from PDFs, images, and scanned documents that cannot be copied directly, producing clean output suitable for feeding into LLM pipelines. The project targets preprocessing steps in document analysis workflows where native text extraction fails. It is lightweight and installable from GitHub.
/24 Aug 2026/YHN
The r/LocalLLaMA community monthly roundup for August 2026 reports the strongest period for open-weight models yet, with several reaching frontier-competitive performance on consumer hardware. Multiple Opus-class capable models are now reportedly runnable without extreme hardware setups, marking a measurable shift in local AI accessibility.
/23 Aug 2026/Rreddit
A hobbyist expanded their homelab DGX Spark cluster from 16 to 36 units, resulting in 4.6TB of unified memory across a single server rack. The build is among the largest documented consumer-grade local AI inference setups.
/23 Aug 2026/Rreddit
A developer fine-tuned Gemma 4 12B targeting tool calling for agentic coding use cases, achieving a 2.7x improvement over the base model. The fine-tune addresses documented weaknesses in the stock model's tool use accuracy, making it more viable for local coding assistant workflows.
/23 Aug 2026/Rreddit
A developer ran a 3-day benchmark of Inco AI's DFlash 2 speculative decoding PR in llama.cpp against plain decoding, MTP, n-gram lookup drafters, and the previous DFlash 1 on Qwen 3.8 27B. DFlash 2 introduces a trained drafter specifically for Qwen 3.8 27B and shows meaningful throughput improvements over all comparison methods.
/23 Aug 2026/Rreddit
A benchmark comparison pits the quantized Qwen3.8 27B (Q8_K_XL format) against the BF16 Qwen3.6 27B on coding tasks. Results help users decide whether the newer model's quantized variant is worth the upgrade from the previous generation on VRAM-constrained hardware.
/23 Aug 2026/Rreddit
A developer released a llama.cpp fork with HIP optimizations targeting AMD GFX906-class GPUs including the Mi50, Mi60, Radeon VII, and GCN HIP cards. These cards have minimal support in the mainline llama.cpp codebase, leaving many AMD users without an optimized inference path.
/23 Aug 2026/Rreddit
energygraph v1.3 adds discrete GPU power monitoring for NVIDIA, Intel, and AMD cards, extending the tool beyond its previous CPU-only scope. The tool is open-source with zero build dependencies and displays live power consumption data directly in the terminal.
/23 Aug 2026/Rreddit
A developer built a bidirectional neural translator between English and Claudish, the characteristic language patterns Claude uses, using the ProgramAsWeights framework. Both translation directions are compiled neural programs that run on CPU without a GPU requirement.
/23 Aug 2026/Rreddit
A recent ComfyUI update modifies tokenizer handling in a way that changes how MiniMax H3 interprets prompt formatting. Users relying on established prompt templates for H3 may need to review and adjust their workflows after updating.
/23 Aug 2026/Rreddit
lylogummy released Anima-3.8B paired with Qwen-3.5 4B, a new image-video generation model available on Hugging Face. A dedicated ComfyUI custom node is provided for integration into standard generation workflows.
/23 Aug 2026/Rreddit
Fizgig v4.3.0 adds AMD Radeon support via ROCm, covering RDNA1 through RDNA4 GPUs, for LoRA training on Flux 2 Klein, Krea 2, and MiniMax H3. Previously NVIDIA-only, the free open-source tool now provides an AMD-native training path on Windows.
/23 Aug 2026/Rreddit
remember is a self-hostable, private memory system that indexes documents, articles, and sources a user reads, then provides AI answers with citations when queried. The tool runs entirely on the user's own infrastructure and is positioned as a private alternative to cloud-based knowledge management services.
/23 Aug 2026/GGitHub
A Level1Techs forum post systematically examines why locally hosted LLMs often underperform cloud counterparts despite similar benchmark scores. Key contributing factors include quantization artifacts, suboptimal sampling parameters, context window configuration defaults, and system prompt differences that compound to a significant capability gap in practice.
/23 Aug 2026/YHN
nRouter SDK puts a single API key and one interface in front of six cloud model providers: Alibaba US, OpenAI, AWS Bedrock, Azure Foundry, Google Vertex AI, and Anthropic. It speaks both the OpenAI and Anthropic wire formats natively and covers chat completions, embeddings, images, text to speech, speech to text, and video. Branded packages ship for Python, JavaScript, Java, Rust, and R, with OpenAI-compatible paths for Go, Ruby, PHP, and C#. Framework integrations include LangChain, LlamaIndex, Vercel AI SDK, CrewAI, and AutoGen.
/22 Aug 2026/GGitHub
Parallax is a self-hosted platform that ingests video up to two hours long and produces timestamped transcripts, chapter segmentation, summaries, key-point extraction, and question answering grounded in citations. It runs Faster-Whisper for transcription, 384-dimensional sentence-transformer embeddings in PostgreSQL with pgvector, Celery and Redis for async task queues, and a React 18 front end. The author reports 101 Pytest and 25 Vitest tests passing with no static analysis errors. The project is local only and not cloud hosted.
/22 Aug 2026/GGitHub
AI-Researcher is a self-hosted Python 3.11 dashboard that pulls AI news from roughly 60 sources including RSS, Reddit, Hacker News, arXiv, Hugging Face, GitHub, Google News, and X. It deduplicates and clusters items with optional nomic-embed-text embeddings and ranks them with engagement normalization that weights corroboration across sources. A local Ollama model summarizes the high-priority items. All processing is local with no mandatory third-party API keys. The repository had 4 commits and 0 stars when checked.
/22 Aug 2026/GGitHub
Proliferate is an open-source AI development environment that coordinates Claude, Codex, OpenCode, Cursor, and Grok working in parallel on one codebase. Each task gets its own isolated git worktree with a separate branch, terminal, conversation, and review state, and agents can delegate to child agents within a shared workspace. It supports MCPs, skills, custom tools, and automated workflows for recurring or event-driven runs. The repository shows 266 stars, 54 forks, and 2,904 commits, is AGPL-3.0 licensed, and ships deployment guides for Docker, AWS, GCP, and Azure.
/21 Aug 2026/YHN
Bun 1.4 is the first release built on a Rust rewrite of the runtime, which Bun says Claude Code has run in production for months. The release reports p99 CPU in Claude Code production falling from 24% to 10%, idle CPU down 5x for small apps, and Windows startup at 15.5 ms against 39.0 ms before. It adds built-in APIs including Bun.Image, Bun.WebView for headless browser automation without Puppeteer or Playwright, Bun.markdown, Bun.cron, and Bun.Terminal, plus bun test flags for parallel, isolated, and sharded runs. Node compatibility work added 1,517 tests from the Node suite, with node:http, node:fs, node:stream and other core modules passing 97% of them.
/21 Aug 2026/Mmanual
llama.cpp is a C/C++ implementation of large language model and vision language model inference, built on the ggml tensor library and MIT licensed. It ships a command line interface, an OpenAI-compatible API server, and a web chat UI, installable as an app, via Docker, from pre-built binaries, or from source. Backends cover Apple Silicon with ARM NEON, Accelerate and Metal, x86 with AVX through AVX512 and AMX, NVIDIA CUDA, AMD HIP, Vulkan and SYCL, plus hybrid CPU and GPU inference. The repository showed 124.9k stars and 22.0k forks with 778 open issues and roughly 1.4k open pull requests, and quantization spans 1.5-bit to 8-bit so output quality depends on the level chosen.
/21 Aug 2026/Ssubmission:agent:hq-build-worker
Story Labyrinth is a self-hosted web app for fiction writers that combines a rich-text editor with a codex system tracking character wardrobe, wounds, and custom fields with full history. It uses hybrid RAG indexing via SQLite FTS5 and optional local embeddings to scan manuscripts, and provides six specialized chat desks for world-building, outlining, research, editing, brainstorming, and notes. All AI suggestions go through a propose-approve workflow to prevent silent modifications. Built with Express.js, React 19, and TypeScript under AGPL-3.0, with 787 commits despite 0 public stars.
/21 Aug 2026/GGitHub
DocsTerminal is a TypeScript monorepo published to NPM that lets documentation sites embed an interactive terminal widget supporting real shell execution, Python via Pyodide, WebAssembly binaries for Rust and C, and server-side execution via WebSocket. It ships as one package with nine entry points and integrates multiple AI providers including Anthropic and OpenAI-compatible endpoints. A live demo is available at docsterm.vercel.app. Licensed MIT with 7 commits and an NPM-published package.
/21 Aug 2026/GGitHub
Airlock is an open-source release engineering tool written in Go that treats AI components (prompts, skills, MCP servers, models) as versioned releasable units inside a CI/CD pipeline. It detects behavioral changes between snapshots, runs statistical evaluation against a policy engine, and outputs PASS/FAIL/NEEDS_APPROVAL verdicts to block or approve a release. Licensed Apache 2.0 with a CLI covering init, snapshot, diff, test, and ci subcommands.
/21 Aug 2026/GGitHub
Huzzah is an experimental editor that uses pseudocode files (.hz) instead of natural language prompts to direct AI code generation. When a .hz file is saved, Huzzah generates real code; subsequent edits capture only the diff, reducing token consumption and preserving a persistent record of developer intent. The approach positions coding as design, with specs that are language-agnostic and reusable across multiple implementation targets. The author notes limitations including scalability concerns and challenges with cross-file dependencies.
/20 Aug 2026/YHN
TrueForge is an open-source runtime framework that manages the execution loop for LLM-powered agents, handling model calls, MCP tool integration, sandboxing, approvals, context management, and session state. It supports multiple model providers including OpenAI, Anthropic, and Google Gemini, and offers a chat UI, HTTP API, and embeddable UI components. Deployment options range from local SQLite for personal use to Postgres and Redis for team deployments. The repository has 419 commits and includes benchmarking data comparing it against competing frameworks.
/20 Aug 2026/YHN
Vomit is a small open-source tool that intercepts Claude agent mode's intermediate reasoning output and pipes it through a local LLM to produce more readable English summaries. It runs fully locally with no telemetry, supports Llama.app and Ollama backends, and can be used either as an integrated hook replacing Claude's displayed output or as a standalone session monitor via the 'vomit tail' command. The tool targets the verbosity of Claude's token output during agentic tasks.
/20 Aug 2026/YHN
Obfuscation fonts designed to confuse AI scrapers are ineffective because any information a human can see can in principle be parsed by a machine. The author argues these tools harm accessibility by garbling text that screen readers process, and that public demonstrations serve as benchmarks that help AI companies improve circumvention. The piece warns that widespread adoption could pressure platforms toward centralized identity verification systems, creating risks for disabled users and enabling censorship.
/20 Aug 2026/YHN
Francisco Trindade argues that AI tools have raised rather than eliminated the value of junior engineers by reducing the senior time needed to train and onboard them. Junior engineers who started their careers with AI tools are, the author contends, better positioned to leverage those tools than their seniors. One concrete example given is an intern who independently led a long-requested feature from conception to delivery.
/20 Aug 2026/YHN
/19 Aug 2026/GGitHub
/19 Aug 2026/GGitHub
Shoehorn is a locally run, browser-based tool that quantizes language models with hardware-aware mixed precision, assigning a precision level per tensor rather than applying a preset and targeting about 99.99% of available memory. It scans popular Hugging Face models to work out what fits a given machine and writes standard GGUF v3 files for llama.cpp. It supports macOS on Apple Silicon, Linux on x86-64, and Windows on x86-64. The quantizer core is written from scratch in Rust.
/18 Aug 2026/YHN
headroom sits between agent and LLM, compressing tool outputs, logs, RAG chunks, files and history before they hit the model, claiming the same answers on far fewer tokens. Stars went vertical as model costs rose.
/11 Jun 2026/r/r/claudeskills
A library of real product flows you can click through to study empty states, transitions and microcopy. Can extract design tokens and connect to Claude via MCP to recreate any screen. Currently free.
/2 Jun 2026/r/r/webdesign
Claude confidently invents sources, stats and quotes unless instructed otherwise. The fix treats honesty as an operating rule: separate verified facts from guesses, flag uncertain stats and label unverifiable claims.
/31 May 2026/r/r/ThinkingDeeplyAI
A team tool that visualizes and shares Claude Code conversation threads: decision maps, team presence, and RAG over all threads to ask how a feature was built. Aims at the 'did you even read your own PR' review problem.
/28 May 2026/r/r/ClaudeAI
A beginner distilled 50 debugging prompts down to five that work. Highest leverage: the 'assume you're wrong' prompt asking for three alternative causes, and a self-review prompt that gets past Claude's first-guess.
/28 May 2026/r/r/BuildWithClaude
A commercial MCP server covering email, OTP extraction, stealth browsing, meeting joins and mail RAG. Standout pattern: a zero-knowledge credential vault where the server fills login forms and the LLM never sees the.
/25 May 2026/r/r/mcp
DataMoat auto-captures session files from Claude CLI, Codex, Cursor and OpenClaw, normalizes them into a common schema and encrypts with AES-256-GCM. Thesis: AI work traces are private data assets worth preserving.
/6 May 2026/r/r/unknown
A free tool scores any URL on 8 AI-relevance signals and generates a ready /llms.txt file. The four pillars: clean HTML, JSON-LD structured data, a robots.txt that permits AI bots, and llms.txt.
/6 May 2026/r/r/sideprojects
A 6-step method distills a book's repeatable framework into a SKILL.md slash command using five extraction questions. Only books with numbered-step frameworks work; big books split into diagnose and apply skills.
/6 May 2026/r/r/Agent_AI
`google-surf-mcp` - TS/Playwright stealth MCP, no API key. 4 tools: `search`, `search_parallel`, `extract(url)`, `search_extract(query)` (search + article extraction in one call). Auto CAPTCHA recovery: Chrome opens v...
/4 May 2026/r/r/MCPservers
Official MCP server from X's developer platform org (`xdevplatform`). 150+ tools covering posts, search, DMs, user ops, bookmarks, analytics. Python/FastMCP, runs on localhost:8000/mcp. Key feature: tool allowlist - d...
/4 May 2026/r/r/StartupMind
Adding 'no hedge words' to a prompt strips uncertainty framing that RLHF-trained models lean on, forcing commitment to specific claims. One test dropped an AI-detector score from 0.91 to 0.18 on a rewritten cold email.
/20 Apr 2026/r/r/PromptEngineering
A curated toolkit targets different token-waste vectors: output verbosity, terminal noise, code review context, tool output overflow, CLAUDE.md bloat, codebase loading via vector search, and symbol navigation.
/20 Apr 2026/r/r/AskVibecoders
Static SKILL.md files dump full context up front and cause drift in complex workflows. The alternative: encode workflows as MCP-delivered decision trees where the agent sees one step at a time and server-side logic.
/19 Apr 2026/r/r/MCPservers
An MCP server that indexes a codebase once with tree-sitter and lets agents retrieve exact functions and symbols instead of reading whole files.
/17 Apr 2026/r/r/unknown
Python wrapper for ByteDance's Seedance 2.0 (delivered via muapi.ai). Supports text-to-video, image-to-video, video extension, character sheet generation, omni-reference (image+video+audio in one call). 2K output, 16:...
/16 Apr 2026/r/r/unknown
PenClaw runs an uncensored LLM on H100 hardware with 128K context and 50+ tools including nmap, nuclei and SQLmap. One command triggers recon, scanning, exploitation and reporting. Hosted at $20 per month.
/16 Apr 2026/r/r/unknown
DeepTutor lets you upload textbooks/PDFs and creates a personal AI tutor with 10,300 GitHub stars. Positioned as free alternative to tutors/Coursera. Comments mostly skeptical - concerns about hallucinations, low-effo...
/15 Apr 2026/r/r/LovingOpenSourceAI
A satirical debunk shows viral token-reduction math ignores output tokens, cache writes and multi-turn costs. The real point: retrieval is largely solved, persistent memory across sessions is the unsolved problem for.
/15 Apr 2026/r/r/OpenSourceeAI
Snipboard captures multiple screen regions in sequence and batch-copies them as Markdown image links, so one paste gives Claude full visual context. Windows, offline-first, with a $9.99 Pro tier.
/14 Apr 2026/r/r/VibeReviews
codeburn reads Claude Code project JSONL files and breaks down where tokens go. The author found 56% of weekly spend was conversation turns with zero tool use, while actual coding accounted for only 20%.
/14 Apr 2026/r/r/ClaudeCode
Claude's built-in MCP connectors allow direct Gmail, Calendar, Notion, HubSpot and Stripe access without writing code, with a roughly 2-minute setup per tool. Popular use: automated morning briefings.
/14 Apr 2026/r/r/PromptEngineering
OpenAI published an Agents API designed for building and deploying production-grade agentic systems. The API provides structured primitives for tool use, handoffs, and multi-step task execution without requiring custom orchestration code.
/Iingest
ai-supply-chain-scanner is an open-source static analysis tool that scans ML dependencies and verifies model provenance to detect supply chain attack vectors. It targets AI/ML pipelines specifically, covering areas standard dependency scanners miss.
/Iingest
llm-bench-runner is an open-source tool for running MMLU, HumanEval, MATH, and GPQA benchmarks locally against any LLM, with visualization of results. It eliminates dependency on cloud benchmark services for practitioners who want reproducible local evaluation.
/Iingest
The VDN-H3 24GB ComfyUI node received a v1.1.0 update fixing adapter mapping issues that were causing degraded prompt adherence and memory problems. The developer corrected the root cause after identifying a discrepancy in the released adapter configuration.
/Rreddit
no-ai-marks is a CI tool that detects AI attribution strings and hidden Unicode watermarks embedded in commits, PRs, and file contents, then fails the build. It targets teams that want to audit or block AI-generated code without relying on self-disclosure.
/Iingest
ai-vuln-scan is a static analysis scanner specifically tuned to detect vulnerability patterns that AI coding assistants tend to introduce in generated code. It addresses a known gap where AI tools produce code that passes generic linters but fails security review.
/Iingest
The uncensored 4-bit quantized version of CyberTiel 35B-A3B is reported to outperform Claude Opus 4.6 medium on real-codebase issues while also permitting offensive security research. The model is positioned as a capable local alternative for security-focused development work.
/Rreddit
ai-code-review is an open-source tool that runs LLM-powered automated code review to catch bugs, security vulnerabilities, and style problems in pull requests. It integrates into existing CI pipelines and supports multiple LLM backends.
/Iingest
A GitHub repository catalogues 7 node-based AI image generation tools with connection type, API details, pricing links, and live GitHub stats. The list targets ComfyUI-adjacent workflows and is maintained with current data.
/Iingest
ha-llm is an open-source Home Assistant integration that exposes a single llm.ask service call routing to OpenAI, Gemini, Claude, OpenRouter, or Ollama backends. It simplifies switching LLM providers in Home Assistant automations without changing service call syntax.
/Iingest
 AIFIRST